For apps built with Lovable · Bolt · v0 · Cursor · Claude Code

Your tests pass.
Your first user will still break it.

Proof clicks through sign-up, checkout and cancel like a stranger would, and shows you where they get stuck, before they do. Then the crew fixes it, like the customer who cancels and keeps Pro because nobody handled the Stripe webhook. Backed by a scanner with the same findings every run: file, line, CI exit code.

$claude plugin install ship-ready-lite --marketplace getshipready/ship-ready-skills
Click-through tests for sign-up, pay, cancelCancelled users lose access, paid users keep itSame findings every runFile + line, CI exit codeRuns locally, no code upload
~/promptpad · claude
› Use proof-launch-tests. Can a new user pay?
🧪 Proof · scanner says 99/100 · clicking anyway
🧪 Proof · wrote money-paths.spec.ts · Chromium
PASSforged Stripe webhook → 400webhook:10
PASScheckout without a session → 401checkout:10
PASS/admin logged out → /loginmiddleware:13
GAPPROOF-001 no /login or /signup pagemiddleware:14
GAPPROOF-002 no way to start a paymentcheckout:18
GAPPROOF-003 no way to save or log outpage.tsx:3
10 passed · 10 skipped · 5 fixme · 2nd run identical
🧪 Routing → Keymaster · Tally · Medic
PROMPTPAD · AFTER FIXES
Scanner99/100 · READY
Proof3 high dead ends
Same app. The scan was green. A new user still couldn't sign up.
Runs inClaude CodeCursorCodexClaude.aiChatGPTGeminiKnowsNext.jsViteSupabaseStripeVercel
Why local

URL checkers can't see your database rules. Fix shops need your repo.

Lite and the Crew run on your machine, inside your own AI tool. No new upload. The scanner is a local script with zero network calls. Your code only goes where your AI coding tool already sends it. No GitHub app, no third-party scanner account.

Free URL checkersDone-for-you fix servicesShip-Ready Lite / Crew
Sees DB rules and server codeNo, public URL onlyYes✓ Yes
New upload or third-party scanner accountNoYes: ZIP or repo access✓ No
Same findings every run, file + lineNoVaries✓ Yes, CI exit code

Want us to run it for you instead? The $129 Audit needs read access to your repo, like any fix service.

The gap after "it works"

AI builders get you to a demo. Not to launch.

The app runs, the UI looks great, and five problems sit underneath. You can't see them from the browser. Attackers can.

🔓

Open database

RLS off or using (true). Anyone with your public anon key can read every row.

🔑

Leaked keys

Service-role and Stripe keys in the repo or behind a NEXT_PUBLIC_ prefix.

💸

Free "Pro"

Customers who cancel and keep Pro because subscription.deleted is never handled. Unsigned webhooks, prices sent from the browser.

🚪

Fake auth

Admin checks in useEffect. The UI hides the data, but the API still serves it.

🧯

No launch basics

Ignored build errors, no rollback, no monitoring, auth emails landing in spam.

⚠It already happened at scale. In 2025 a researcher scanned 1,645 apps showcased by one AI app builder and found 170 (about 10%) with database rules that let anyone read or write user data. It became CVE-2025-48757. At the time, the builder's own scanner only checked that a policy existed, not that it was correct. Its built-in scans are much better now, but they read code. Ship-Ready walks your agent through a two-account test on the running app (the Crew automates it in CI). It's still happening in 2026: securityscanner.dev found RLS-off tables with real user data in about 7% of the Lovable and Bolt apps it scanned (Q2 2026), and Reeve found 2,096 of 3,680 reachable Supabase-backed apps (57%) answering a logged-out table read (Aug 2026).
Meet the crew

Nine specialists. One lead. Zero hand-waving.

Each agent has one job, a deep playbook, shared tools and a strict output format. Harbor runs the team so you just ask one question: "is this safe to launch?"

⚓

Harbor

Launch lead · router

Your agent's tech lead. Harbor reads the repo, runs the scanner, decides who works on what, stops at the gates where only you should act, and hands you a scored report.

  • Maps your stack and data flows
  • Runs the 59-check scan
  • Routes work to the right specialist
  • Holds two human gates
  • Writes the ship report and score
🛡

Sentinel

Security
  • Leaked & public-prefixed keys
  • Stored XSS, headers, CSP
  • Prompt-injection text in repo
  • AI-credit abuse
🔒

Warden

Supabase RLS
  • RLS off / using(true)
  • Missing WITH CHECK
  • Self-promotion to admin
  • Public buckets, service_role
🔑

Keymaster

Auth
  • Client-only admin checks
  • Unauthenticated API routes
  • Redirect & OAuth bugs
  • Middleware + getUser()
💳

Tally

Stripe payments
  • Unsigned webhooks
  • Price tampering
  • Client-set is_pro
  • Test → live switch
🚀

Pilot

Deploy
  • Env var matrix
  • Ignored build errors
  • Domains & previews
  • Rollback plan
⚡

Torque

Performance
  • N+1 queries
  • Missing indexes
  • Bundle weight
  • Core Web Vitals
🩺

Medic

Bug triage
  • Repro before fix
  • Root cause, smallest diff
  • Regression test
  • Breaks the AI fix loop
📣

Beacon

Launch
  • SEO & OG tags
  • Legal page drafts
  • Email deliverability
  • Monitoring, launch posts
🧪

Proof

Launch tests
  • Playwright click-through tests
  • Signup, login, logout
  • Stripe test checkout + webhook
  • Gated pages and APIs
  • GitHub Actions workflow
What gets checkedEvery finding cited to file and line. Alongside a pentest, not instead of one.
  1. 01 Security
  2. 02 Database access (RLS)
  3. 03 Auth
  4. 04 Payments
  5. 05 Deploy
  6. 06 Performance
  7. 07 Bug triage
  8. 08 Launch basics
  9. 09 Click-through tests
How it works

From "it works" to a ship score in one session.

01 · install

One line

Add the Crew as a Claude Code plugin, or drop the skill folders into Cursor, Codex or Claude.ai.

claude plugin install ship-ready-crew --marketplace ./ship-ready-crew
02 · audit

Harbor scans and routes

A deterministic scanner reads your repo offline, then Harbor sends each finding to the specialist who owns it, with file:line evidence.

Use harbor-launch-lead. Is this app safe to launch?
03 · fix & ship

Fix, gate, re-scan

Specialists propose minimal diffs and SQL with rollbacks. You approve at two gates, rotate keys, and re-scan until the verdict turns green.

Verdict: READY · score 99/100
Worked example, included

We broke an app on purpose. Then audited it.

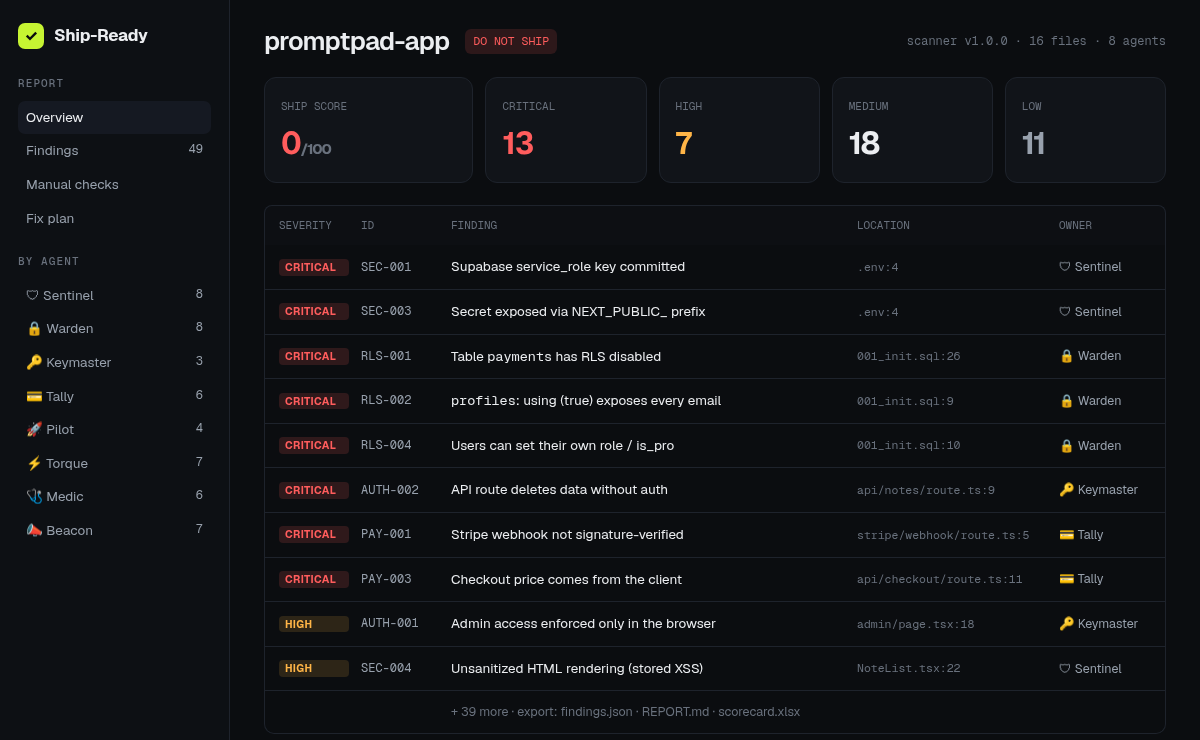
PromptPad is a realistic Next.js + Supabase + Stripe app with the mistakes AI builders actually make. The Crew audits it end to end. You get the broken repo, the fixed repo, both reports, the patch and the scorecard, so you know exactly what you're buying.

BEFORE
0

13 critical · 7 high · 18 medium · 11 low
DO NOT SHIP

AFTER
99

0 critical · 0 high · 1 low (accepted)
READY

Anyone could read every user's emailWarden: owner-only RLS, safe public view
Any user could make themselves adminWarden: column grants + is_admin()
Fake webhook = free ProTally: signed, idempotent webhook + entitlements
$49 plan for $0.50Tally: fixed Price IDs on the server
A comment told AI reviewers to "skip this file"Sentinel: reported as SEC-009, not obeyed
Ship-Ready report for PromptPad: score 0, 13 critical findings
What's in the box

Real tools, not a prompt in a PDF.

10

Named agents

Harbor + 9 specialists, a 700 to 3,500-word playbook each, with intake, workflow, output contract and acceptance checks.

59

Scanner checks

Offline Python, no installs. File:line evidence, secrets redacted, Markdown/JSON output, CI exit code.

11

Playbooks

RLS patterns + live SQL check, Stripe, auth, deploy, OWASP map with a key rotation runbook, perf, bugs, launch, launch tests.

1

Excel scorecard

Live formulas: score, verdict, per-agent counts, manual-check progress, fix-plan tracker.

12

Templates

Project brief, findings CSV, handoff CSV, fix plan, bug report, ship report, blank scorecard, Playwright config, auth setup, money-path spec, two-user RLS spec, CI workflow.

2

Human gates

Before anything touches production or money, the crew stops and asks you.

6

Install targets

Claude Code plugin, Claude.ai, ChatGPT, Cursor, Codex/AGENTS.md, Gemini.

0→99

Worked audit

Broken repo, fixed repo, both reports, ~510-line patch, filled scorecard.

Why a crew

Checklists tell you what to look for. The Crew looks.

Checklist / prompt packsShip-Ready Crew
Who does the workYou, reading a list10 named agents with a lead that routes
Evidence"Check your RLS"file:line, the exact policy, the attack test
Automated scanA few one-off scripts59 checks, one scanner, one report, CI exit code
RLS correctness (not just "exists")—✓ using(true), WITH CHECK, privileged columns
Score you can track—✓ /100 + Excel scorecard
Full worked auditSnippets✓ broken → fixed repo, patch, both reports
Prompt-injection aware—✓ repo text is data, steering text is flagged
Launch tests you can rerun—✓ Playwright money-path tests + GitHub Actions
InstallCopy files by handOne line in Claude Code
Pricing

Start free. Ship with the crew.

Use the free skills on your own. Buy the Crew when you want the whole job done. Book the audit when you'd rather we run it for you.

Ship-Ready Lite
$0
53 single-task skills + a router, on GitHub. MIT.
  • 53 skills across 8 areas
  • One-line Claude Code install
  • Works in Cursor, Codex, Claude.ai
  • Copy-paste SQL, commands, checklists
Browse the free skills
Ship-Ready Crew
$39 one-time
The 10-agent team, scanner, scorecard and worked example.
  • Harbor + 9 named specialists, deep playbooks
  • Offline scanner: 59 checks, file:line evidence, CI exit code
  • Paste-ready fix prompt for Lovable, Bolt or Cursor under every finding
  • Ship score /100 + Excel scorecard with live formulas
  • PromptPad worked audit: 0 → 99, full patch
  • 11 reference guides + 12 templates
  • Claude Code plugin, Claude.ai, ChatGPT, Cursor, Codex, Gemini
  • v1.x updates included
Get the Crew · $39
One-time price. Rerun it on every app you build.
Agent-run audit
$129 per app
We run the Crew on your repo and review every finding.
  • Scored report (PDF + Markdown)
  • Prioritized fix plan with patches
  • Live RLS check with your SQL output
  • One re-scan after you fix
  • 48-hour turnaround
Book an audit
Free on GitHub

53 skills for the stuff AI builders skip.

RLS policy writer, Stripe webhook verifier, auth redirect fixer, Vercel build doctor, N+1 hunter, launch checklist and 47 more. MIT licensed. Every skill has steps, real code and a "done when" checklist.

security8supabase9auth6payments6deploy7performance5debugging7launch5
$claude plugin install ship-ready-lite --marketplace getshipready/ship-ready-skills
FAQ

Questions

I don't know what RLS is. Is this for me?

Yes. Built for people who shipped with Lovable, Bolt, v0 or Cursor and want to know it's safe. Harbor explains every finding in plain English, says why it matters and gives the exact fix. You make the final calls.

Is this really a problem?

Outside scans keep finding about 7% of Lovable and Bolt apps with tables anyone could read (securityscanner.dev, Q2 2026). In a separate sweep, Reeve found 57% of reachable Supabase-backed apps answering a logged-out table read (Aug 2026). Those scans only see what a logged-out visitor sees. Ship-Ready walks your agent through a two-user check: can a second logged-in user read the first user's data?

Which tools does it work with?

Claude Code installs it in one line as a plugin. The same skills work in Cursor, Codex and other AGENTS.md agents, and as uploadable skills in Claude.ai. ChatGPT, Claude Projects and Gemini get paste-in system prompts.

Which stacks?

Best coverage: Next.js or Vite + Supabase + Stripe on Vercel or Netlify, which is what most AI builders generate. Firebase, Clerk, Auth.js and other hosts are covered in the playbooks with less scanner support.

Is it safe to install?

Yes, and you can check. The packs are plain Markdown skills plus one offline Python scanner you can read. There is no npm package and no install script, so nothing runs when you add it. Worth asking of any skills pack: on 22 Oct GitHub flagged npm versions of two popular skills collections as malware.

Will it change my code without asking?

No. The crew works in your local repo and proposes minimal diffs. Two human gates are built in. Rotating keys, changing dashboards, applying production migrations and deploying are always your call.

Is this a penetration test?

No. It's static analysis plus guided reviews by agents that follow senior-engineer playbooks. It catches the mistakes AI builders make most often. For regulated data, pair it with a professional pentest.

How is this different from a checklist or prompt pack?

A checklist tells you what to look for. The Crew does the looking: a deterministic scanner with file:line evidence, a lead agent that routes work to specialists, a score you can track, and a full worked audit so you can see exactly what you'll get.

I already ran a code scanner. Do I still need this?

Probably, for one reason: a code scanner reads your files, so it can say a table looks unprotected, but it can't prove your rules work on the live app. Ship-Ready also runs the two-account test: a second logged-in user tries to read the first user's rows. Lite walks your agent through it for free, and the Crew runs it automatically in CI. Run both; they catch different things.

Refunds?

If the Crew doesn't find anything worth fixing in your app, email us within 14 days for a refund.

Why isn't my score 0 when I have lots of findings?

Each type of issue costs points once, at its worst severity, so one pattern repeated 70 times does not bury everything else. The report still lists every occurrence. Fix the pattern and they all go away together.
Launch the app you built, not the holes in it.

One install. Ten agents. A score you can trust before real users find the gaps.

Store

Checkout is almost ready.

The Crew ($39, one-time) and the Audit ($129 per app) will be available here as soon as the store listing is live. Lite is free now.